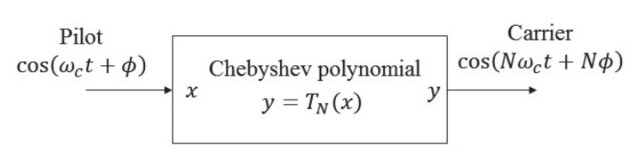Joshua Peter Ebenezer

Senior Computer Vision and Machine Learning Engineer at Apple

I’m currently a Senior Computer Vision and Machine Learning Engineer at Apple, working on Generative AI for images in the Creator Studio Apps team. I was previously Staff Research Engineer II at Samsung Research, where I worked on commercial camera projects (Telephoto Zoom, Night mode) and Generative AI for flagship phones in the Mobile Processor Innovation (MPI) Lab. I completed my PhD at the Laboratory for Image and Video Engineering (LIVE) at UT Austin (2019–2023) under Prof. Alan Bovik and served as Assistant Director of LIVE from 2020–2023.

My research interests include computational photography, image and video quality assessment, and deep learning. I received a B.Tech. from IIT Kharagpur and my PhD thesis focused on no-reference video quality assessment for livestreamed high-motion and HDR videos (sponsored by Amazon Prime Video).

Outside research, I enjoy playing keyboard and guitar, reading theology, history, and philosophy, and volunteering. During my time at UT Austin I served as President of the Austin chapter of Bridges International.

Email  /  CV  /  Google Scholar  /  GitHub  /  LinkedIn

Photo of Joshua Peter Ebenezer

Product Impact

Computational photography algorithms developed at Samsung Research and shipped in Galaxy flagship cameras.

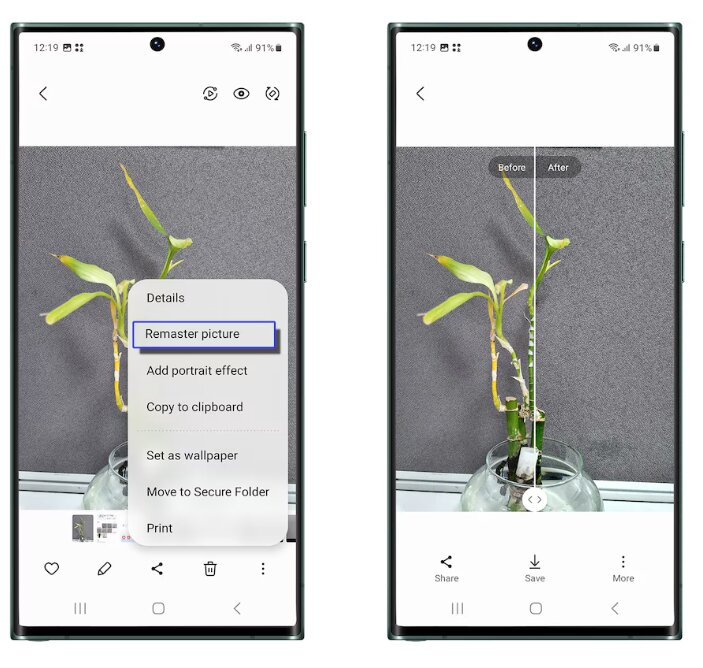
Generative Remaster in Samsung Gallery on Samsung Gallery
Generative Remaster in Samsung Gallery
Samsung Gallery, 2026

Led the generative image restoration team behind the Remaster feature in Samsung Gallery. Adapted vision foundation models for restoration and distilled them into fast single-step models for cloud and on-device deployment.

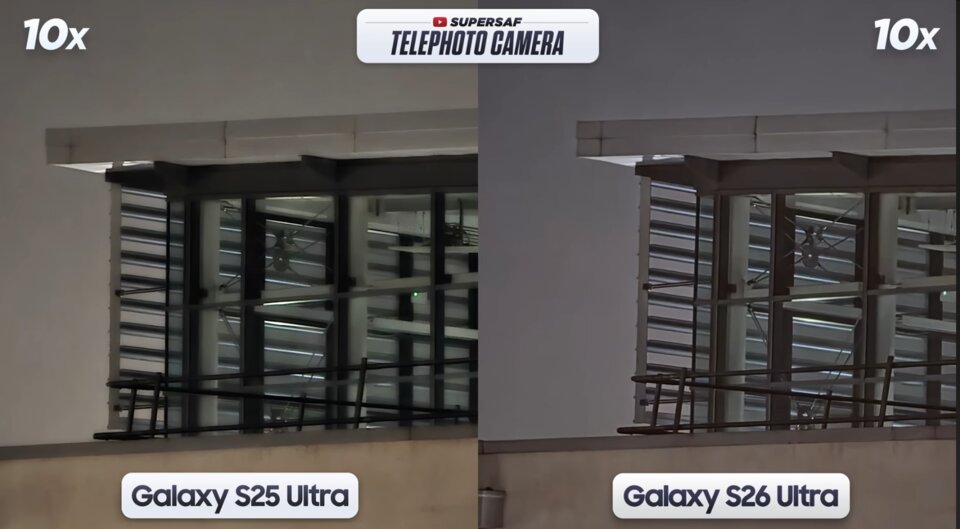
Night Mode on Galaxy S26 series
Night Mode
Galaxy S26 series, 2025

Designed the training pipelines (data rendering and loss functions) for the deep-learning multi-frame Night mode networks on the Galaxy S26 series. Trained the end-to-end systems for the Tele1 and Max Mode features of Night mode, deployed on both Snapdragon and Exynos.

Image: SuperSaf
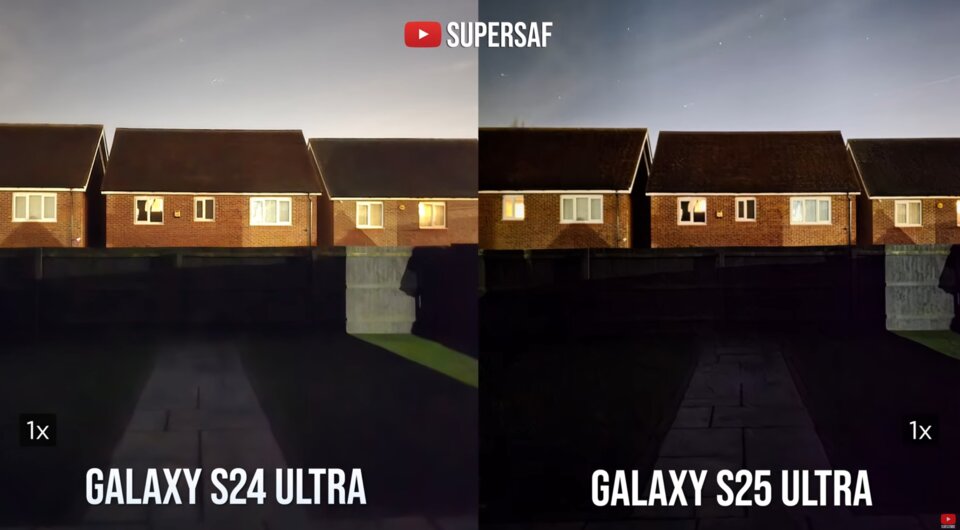
Night Mode on Galaxy S25 series
Night Mode
Galaxy S25 series, 2024

Developed training techniques for the deep-learning multi-frame Night mode pipeline that shipped on the Galaxy S25 series, improving low-light captures from the 1x camera.

Image: SuperSaf
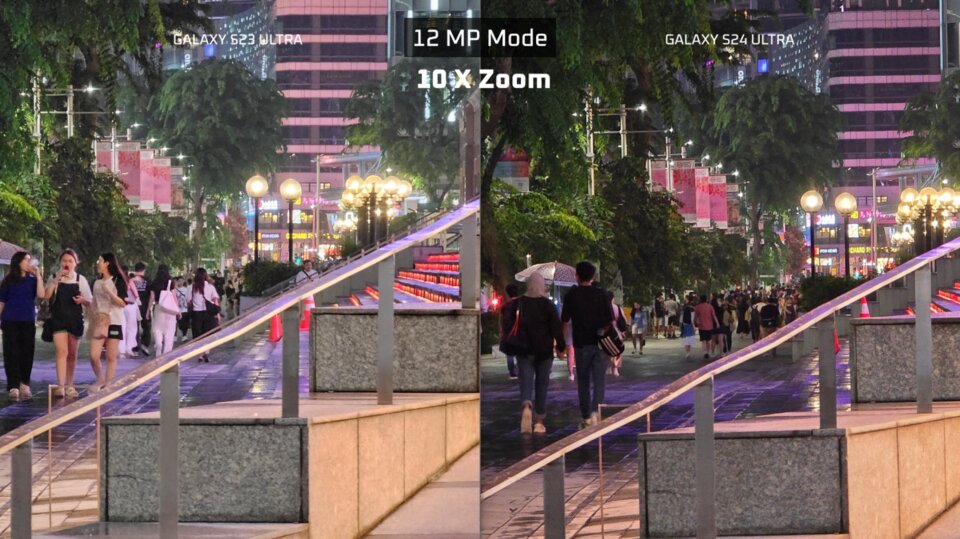
Telephoto Zoom (10x–100x) on Galaxy S24 Ultra
Telephoto Zoom (10x–100x)
Galaxy S24 Ultra, 2023

Developed image registration algorithms for the multi-frame super-resolution pipeline behind 10x–100x zoom on the Galaxy S24 Ultra, along with filtering methods that balance detail generation against fidelity.

Research

My research spans computational photography, image and video quality assessment, and deep learning.

Soumendu Majee*, Joshua Peter Ebenezer*, Abhinau K Venkataramanan, Weidi Liu, Thilo Balke, Zeeshan Nadir, Sreenithy Chandran, Seok-Jun Lee, Hamid Rahim Sheikh
* Equal contribution
CVPR Workshops (CVPRW), 2026

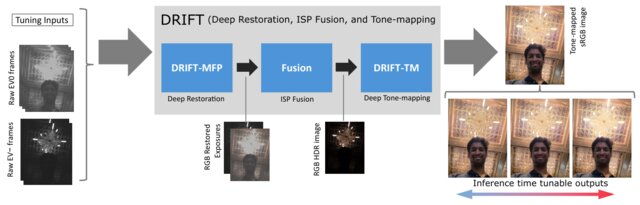
Smartphone cameras have gained immense popularity with the adoption of high-resolution and high-dynamic range imaging. As a result, high-performance camera Image Signal Processors (ISPs) are crucial in generating high-quality images for the end user while keeping computational costs low. In this paper, we propose DRIFT (Deep Restoration, ISP Fusion, and Tone-mapping): an efficient AI mobile camera pipeline that generates high quality RGB images from hand-held raw captures. The first stage of DRIFT is a Multi-Frame Processing (MFP) network that is trained using a adversarial perceptual loss to perform multi-frame alignment, denoising, demosaicing, and super-resolution. Then, the output of DRIFT-MFP is processed by a novel deep-learning based tone-mapping (DRIFT-TM) solution that allows for tone tunability, ensures tone-consistency with a reference pipeline, and can be run efficiently for high-resolution images on a mobile device. We show qualitative and quantitative comparisons against state-of-the-art MFP and tone-mapping methods to demonstrate the effectiveness of our approach.

Harshana Weligampola, Joshua Peter Ebenezer, Weidi Liu, Abhinau K Venkataramanan, Sreenithy Chandran, Seok-Jun Lee, Hamid Rahim Sheikh
CVPR Workshops (CVPRW), 2026

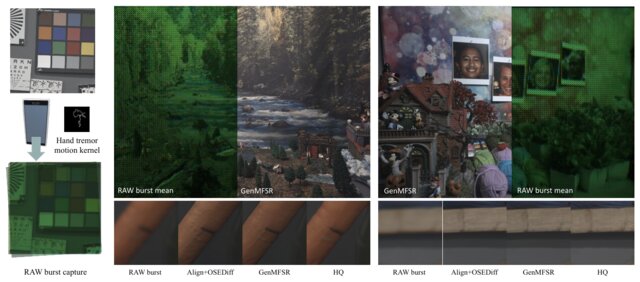
Camera pipelines receive raw Bayer-format frames that need to be denoised, demosaiced, and often super-resolved. Multiple frames are captured to utilize natural hand tremors and enhance resolution. Multi-frame super-resolution is therefore a fundamental problem in camera pipelines. Existing adversarial methods are constrained by the quality of ground truth. We propose GenMFSR, the first Generative Multi-Frame Raw-to-RGB Super Resolution pipeline, that incorporates image priors from foundation models to obtain sub-pixel information for camera ISP applications. GenMFSR can align multiple raw frames, unlike existing single-frame super-resolution methods, and we propose a loss term that restricts generation to high-frequency regions in the raw domain, thus preventing low-frequency artifacts.

Fadeel Sher Khan, Joshua Ebenezer, Hamid Sheikh, Seok-Jun Lee
CVPR Workshops (CVPRW), 2025

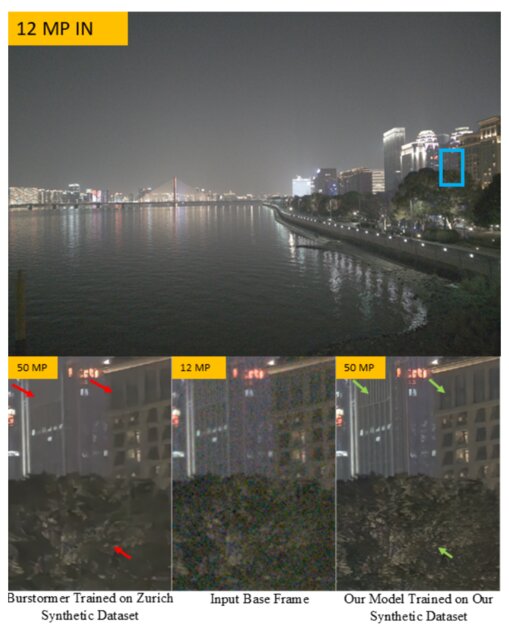
Smartphone cameras have become ubiquitous imaging tools, yet their small sensors and compact optics often limit spatial resolution and introduce distortions. Combining information from multiple low-resolution (LR) frames to produce a high-resolution (HR) image has been explored to overcome the inherent limitations of smartphone cameras. Despite the promise of multi-frame super-resolution (MFSR), current approaches are hindered by datasets that fail to capture the characteristic noise and motion patterns found in real-world handheld burst images. In this work, we address this gap by introducing a novel synthetic data engine that uses multi-exposure static images to synthesize LR-HR training pairs while preserving sensor-specific noise characteristics and image motion found during handheld burst photography. We also propose MFSR-GAN: a multi-scale RAW-to-RGB network for MFSR. Compared to prior approaches, MFSR-GAN emphasizes a "base frame" throughout its architecture to mitigate artifacts. Experimental results on both synthetic and real data demonstrates that MFSR-GAN trained with our synthetic engine yields sharper, more realistic reconstructions than existing methods for real-world MFSR.

Joshua P Ebenezer*, Zaixi Shang*, Yongjun Wu, Hai Wei, Sriram Sethuraman, Alan C Bovik
* Equal contribution
Signal Processing: Image Communication, 2024

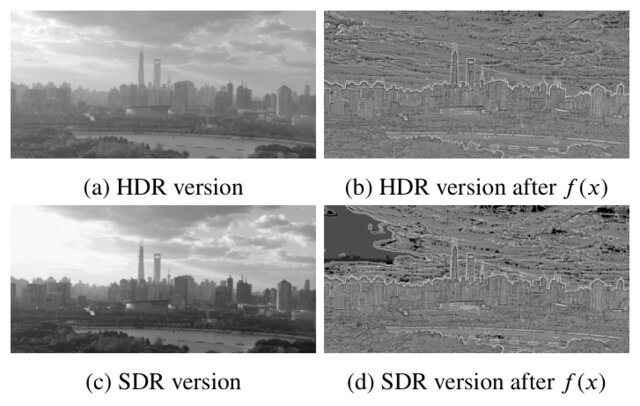
We present a no-reference video quality model and algorithm that delivers standout performance for High Dynamic Range (HDR) videos, which we call HDR-ChipQA. HDR videos represent wider ranges of luminances, details, and colors than Standard Dynamic Range (SDR) videos. The growing adoption of HDR in massively scaled video networks has driven the need for video quality assessment (VQA) algorithms that better account for distortions on HDR content. In particular, standard VQA models may fail to capture conspicuous distortions at the extreme ends of the dynamic range, because the features that drive them may be dominated by distortions that pervade the mid-ranges of the signal. We introduce a new approach whereby a local expansive nonlinearity emphasizes distortions occurring at the higher and lower ends of the local luma range, allowing for the definition of additional quality-aware features that are computed along a separate path. These features are not HDR-specific, and also improve VQA on SDR video contents, albeit to a reduced degree. We show that this preprocessing step significantly boosts the power of distortion-sensitive natural video statistics (NVS) features when used to predict the quality of HDR content. In similar manner, we separately compute novel wide-gamut color features using the same nonlinear processing steps. We have found that our model significantly outperforms SDR VQA algorithms on the only publicly available, comprehensive HDR database, while also attaining state-of-the-art performance on SDR content.

Abhinau K Venkataramanan, Zaixi Shang, Joshua P Ebenezer, Meixu Chen, Zhengzhong Tu, Alan C Bovik
Computer Vision: Challenges, Trends, and Opportunities (book chapter), 2024

Assessing and optimizing the perceptual quality of media plays an important role in enhancing the subjective experiences of hundreds of millions of television, streaming, and social media viewers. Quality assessment methods may be broadly categorized into “subjective” and “objective” methods. Subjective quality assessment consists of conducting studies where participants manually rate the quality of media. On the other hand, objective quality models consist of algorithms designed to accurately predict subjective quality. In this chapter, we will discuss the challenges in assessing the quality of popular visual media, including streaming video, virtual reality, high-dynamic-range, high-framerate, and user-generated video. In particular, we will discuss subjective databases and state-of-the-art quality models that have been developed to address the problem of quality assessment. Finally, we will discuss future trends and open problems that are interesting to tackle.

Joshua P Ebenezer*, Zaixi Shang*, Yixu Chen, Yongjun Wu, Hai Wei, Sriram Sethuraman, Alan C Bovik
* Equal contribution
IEEE Transactions on Image Processing, 2024

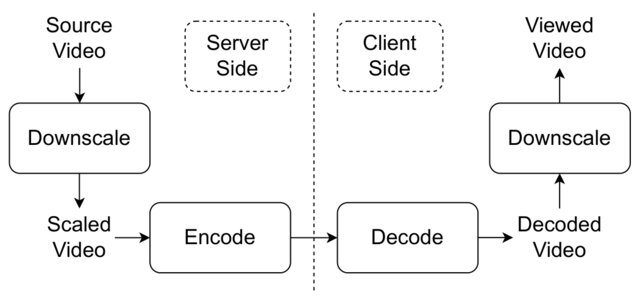
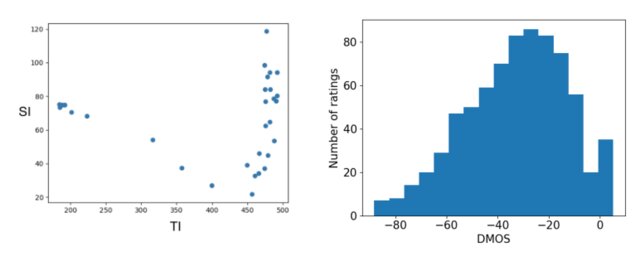
We conducted a large-scale study of human perceptual quality judgments of High Dynamic Range (HDR) and Standard Dynamic Range (SDR) videos subjected to scaling and compression levels and viewed on three different display devices. HDR videos are able to present wider color gamuts, better contrasts, and brighter whites and darker blacks than SDR videos. While conventional expectations are that HDR quality is better than SDR quality, we have found subject preference of HDR versus SDR depends heavily on the display device, as well as on resolution scaling and bitrate. To study this question, we collected more than 23,000 quality ratings from 67 volunteers who watched 356 videos on OLED, QLED, and LCD televisions. Since it is of interest to be able to measure the quality of videos under these scenarios, e.g. to inform decisions regarding scaling, compression, and SDR vs HDR, we tested several well-known full-reference and no-reference video quality models on the new database. Towards advancing progress on this problem, we also developed a novel no-reference model called HDRPatchMAX, that uses both classical and bit-depth sensitive distortion statistics more accurately than existing metrics.
Zaixi Shang*, Joshua P Ebenezer*, Abhinau K Venkataramanan, Yongjun Wu, Hai Wei, Sriram Sethuraman, Alan C Bovik
* Equal contribution
IEEE Transactions on Image Processing, 2023

As compared to standard dynamic range (SDR) videos, high dynamic range (HDR) content is able to represent and display much wider and more accurate ranges of brightness and color, leading to more engaging and enjoyable visual experiences. HDR also implies increases in data volume, further challenging existing limits on bandwidth consumption and on the quality of delivered content. Perceptual quality models are used to monitor and control the compression of streamed SDR content. A similar strategy should be useful for HDR content, yet there has been limited work on building HDR video quality assessment (VQA) algorithms. One reason for this is a scarcity of highquality HDR VQA databases representative of contemporary HDR standards. Towards filling this gap, we created the first publicly available HDR VQA database dedicated to HDR10 videos, called the Laboratory for Image and Video Engineering (LIVE) HDR Database. It comprises 310 videos from 31 distinct source sequences processed by ten different compression and resolution combinations, simulating bitrate ladders used by the streaming industry. We used this data to conduct a subjective quality study, gathering more than 20,000 human quality judgments under two different illumination conditions. To demonstrate the usefulness of this new psychometric data resource, we also designed a new full-reference (FR) HDR VQA algorithm called HDR-VMAF, extending the widely-deployed Video Multimethod Assessment Fusion (VMAF) model using a nonlinear transform to highlight distortions on HDR-enhanced areas. We show that HDR-VMAF provides significantly elevated performance on both HDR and SDR videos, exceeding prior state-of-the-art model performance.

Joshua P Ebenezer, Zaixi Shang, Yongjun Wu, Hai Wei, Sriram Sethuraman, Alan C Bovik
IEEE Signal Processing Letters, 2023

We introduce a novel feature set, which we call HDRMAX features, that when included into Video Quality Assessment (VQA) algorithms designed for Standard Dynamic Range (SDR) videos, sensitizes them to distortions of High Dynamic Range (HDR) videos that are inadequately accounted for by these algorithms. While these features are not specific to HDR, and also augment the equality prediction performances of VQA models on SDR content, they are especially effective on HDR. HDRMAX features modify powerful priors drawn from Natural Video Statistics (NVS) models by enhancing their measurability where they visually impact the brightest and darkest local portions of videos, thereby capturing distortions that are often poorly accounted for by existing VQA models. As a demonstration of the efficacy of our approach, we show that, while current state-of-the-art VQA models perform poorly on 10-bit HDR databases, their performances are greatly improved by the inclusion of HDRMAX features when tested on HDR and 10-bit distorted videos.

Joshua Peter Ebenezer
PhD Dissertation, The University of Texas at Austin, 2023

Video content continues to proliferate, already accounting for more than 70% of internet traffic, and projected to exceed 82% of internet traffic by 2021. Distortions can affect videos as they are captured, transmitted, and received. It is of vital importance to providers of video content to be able to monitor and predict the perceptual quality of their videos, since this directly impacts customer satisfaction. Video quality tools can also help make well-informed design choices while creating systems for capturing, processing, transmitting, and displaying videos. Video quality assessment algorithms also have applications in video denoising, designing loss functions for deep learning, video compression, and many other high-impact areas.

Joshua Peter Ebenezer
arXiv preprint, 2022

This paper presents the results of a study conducted on the perceptual acceptability of audio-video desynchronization for sports videos. The study was conducted with 45 videos generated by applying 8 audio-video offsets on 5 source contents. 20 subjects participated in the study. The results show that humans are more sensitive to audio-video offset errors for speech stimuli, and the complex events that occur in sports broadcasts have higher thresholds of acceptability. This suggests the tuning of audio-video synchronization requirements in broadcasting to the content of the broadcast.

Zaixi Shang*, Joshua P Ebenezer*, Alan C Bovik, Yongjun Wu, Hai Wei, Sriram Sethuraman
* Equal contribution
IEEE International Conference on Image Processing (ICIP), 2022

High Dynamic Range (HDR) videos can represent a much greater range of brightness and color than Standard Dynamic Range (SDR) videos and are rapidly becoming an industry standard. HDR videos have more challenging capture, transmission, and display requirements than legacy SDR videos. With their greater bit depth, advanced electro-optical transfer functions, and wider color gamuts, comes the need for video quality algorithms that are specifically designed to predict the quality of HDR videos. Towards this end, we present the first publicly released large-scale subjective study of HDR videos. We study the effect of distortions such as compression and aliasing on the quality of HDR videos. We also study the effect of ambient illumination on perceptual quality of HDR videos by conducting the study in both a dark lab environment and a brighter living-room environment. A total of 66 subjects participated in the study and more than 20,000 opinion scores were collected, which makes this the largest in-lab study of HDR video quality ever. We anticipate that the dataset will be a valuable resource for researchers to develop better models of perceptual quality for HDR videos.

Joshua P Ebenezer, Yixu Chen, Yongjun Wu, Hai Wei, Sriram Sethuraman
IEEE International Conference on Image Processing (ICIP), 2022

Videos often have to be transmitted and stored at low bitrates due to poor network connectivity during adaptive bitrate streaming. Designing optimal bitrate ladders that would select the perceptually-optimized resolution, frame-rate, and compression level for low-bitrate videos for adaptive streaming across the internet is therefore a task of great interest. Towards that end, we conducted the first large-scale study of medium and low-bitrate videos from live sports for two codecs (Elemental AVC and HEVC) and created the Amazon Prime Video Low-Bitrate Sports (APV LBS) dataset. The study involved 94 participants and 742 videos, with more than 23,000 human opinion scores collected in total. We analyzed the data obtained and we also conducted an extensive evaluation of objective Video Quality Assessment (VQA) algorithms and benchmarked their performance, and make recommendations on bitrate ladder design. We're making the metadata and VQA features available at https://github.com/JoshuaEbenezer/lbmfr-public.

Bijaylaxmi Das, Joshua Peter Ebenezer, Sudipta Mukhopadhyay
The Visual Computer, 2022

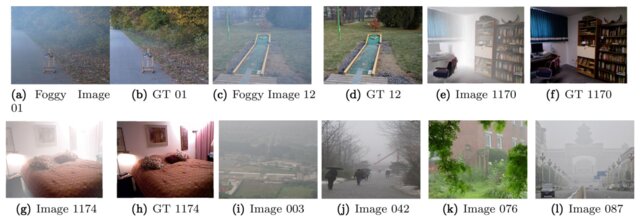
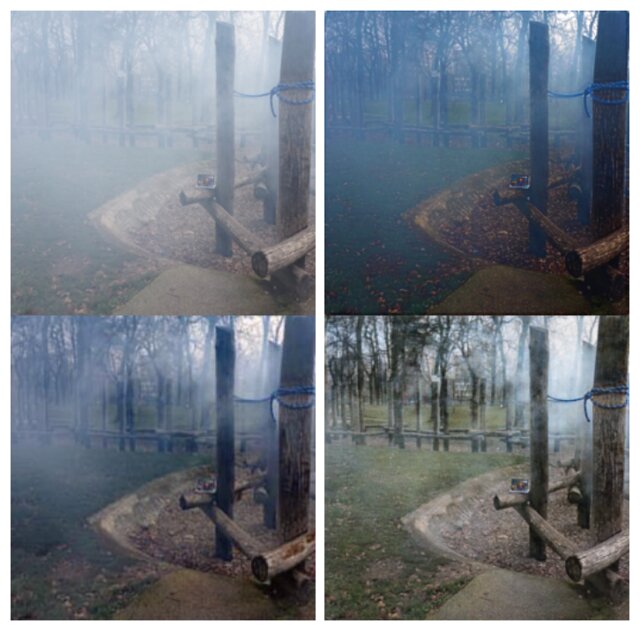
The presence of fog degrades visibility in natural scene conditions. Computer vision applications like navigation, tracking, and surveillance need clear atmospheric images or videos as prerequisites for optimal performance. However, foggy atmosphere creates problems for computer vision applications due to reduced visibility. Different fog removal techniques are used to improve the visual quality of images and videos. The fog density depends on the depth information. Scene depth information estimation needs multiple images, which limits its real-life application. Hence, a single image fog removal requires some prior knowledge and/or assumptions to get the depth information. In this paper, the recent fog removal techniques are grouped into three broad categories: (1) filter-based methods, (2) color correction based methods, and (3) learning-based methods, for ease of understanding. The primary objective is to provide an introduction to this field and compare performance (both qualitative and quantitative) of representative techniques for each category. It is found that filter-based methods are doing overall better compared to other categories.

Zaixi Shang*, Joshua Peter Ebenezer*, Yongjun Wu, Hai Wei, Sriram Sethuraman, Alan C Bovik
* Equal contribution
IEEE Transactions on Image Processing, 2021

Video livestreaming is gaining prevalence among video streaming services, especially for the delivery of live, high motion content such as sporting events. The quality of these livestreaming videos can be adversely affected by any of a wide variety of events, including capture artifacts, and distortions incurred during coding and transmission. High motion content can cause or exacerbate many kinds of distortion, such as motion blur and stutter. Because of this, the development of objective Video Quality Assessment (VQA) algorithms that can predict the perceptual quality of high motion, live streamed videos is greatly desired. Important resources for developing these algorithms are appropriate databases that exemplify the kinds of live streaming video distortions encountered in practice. Towards making progress in this direction, we built a video quality database specifically designed for live streaming VQA research. The new video database is called the Laboratory for Image and Video Engineering (LIVE) Livestream Database. The LIVE Livestream Database includes 315 videos of 45 source sequences from 33 original contents impaired by 6 types of distortions. We also performed a subjective quality study using the new database, whereby more than 12,000 human opinions were gathered from 40 subjects. We demonstrate the usefulness of the new resource by performing a holistic evaluation of the performance of current state-of-the-art (SOTA) VQA models. We envision that researchers will find the dataset to be useful for the development, testing, and comparison of future VQA models. The LIVE Livestream database is being made publicly available for these purposes at https://live.ece. utexas.edu/research/LIVE_APV_Study/apv_index.html

Joshua Peter Ebenezer*, Zaixi Shang*, Yongjun Wu, Hai Wei, Sriram Sethuraman, Alan C Bovik
* Equal contribution
IEEE Transactions on Image Processing, 2021

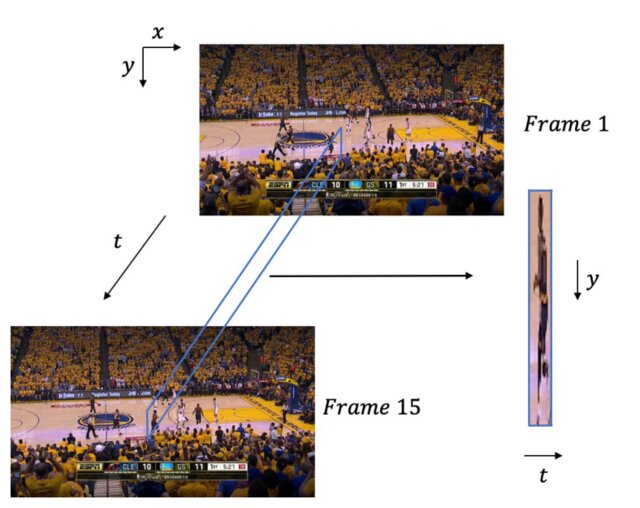
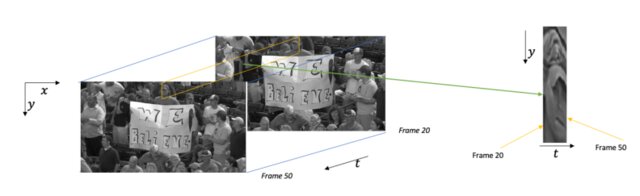
We propose a new model for no-reference video quality assessment (VQA). Our approach uses a new idea of highly-localized space-time (ST) slices called Space-Time Chips (ST Chips). ST Chips are localized cuts of video data along directions that \textit{implicitly} capture motion. We use perceptually-motivated bandpass and normalization models to first process the video data, and then select oriented ST Chips based on how closely they fit parametric models of natural video statistics. We show that the parameters that describe these statistics can be used to reliably predict the quality of videos, without the need for a reference video. The proposed method implicitly models ST video naturalness, and deviations from naturalness. We train and test our model on several large VQA databases, and show that our model achieves state-of-the-art performance at reduced cost, without requiring motion computation.

Zaixi Shang, Joshua P Ebenezer, Alan C Bovik, Yongjun Wu, Hai Wei, Sriram Sethuraman
Picture Coding Symposium (PCS), 2021

Video live streaming is gaining prevalence among video streaming services, especially for the delivery of popular sporting events. Many objective Video Quality Assessment (VQA) models have been developed to predict the perceptual quality of videos. Appropriate databases that exemplify the distortions encountered in live streaming videos are important to designing and learning objective VQA models. Towards making progress in this direction, we built a video quality database specifically designed for live streaming VQA research. The new video database is called the Laboratory for Image and Video Engineering (LIVE) Live stream Database. The LIVE Livestream Database includes 315 videos of 45 contents impaired by 6 types of distortions. We also performed a subjective quality study using the new database, whereby more than 12,000 human opinions were gathered from 40 subjects. We demonstrate the usefulness of the new resource by performing a holistic evaluation of the performance of current state-of-the-art (SOTA) VQA models. The LIVE Livestream database is being made publicly available for these purposes at https://live.ece.utexas.edu/research/LIVE_APV_Study/apv_index.html.

Joshua P Ebenezer, Yongjun Wu, Hai Wei, Sriram Sethuraman, Zongyi Liu
IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), 2021

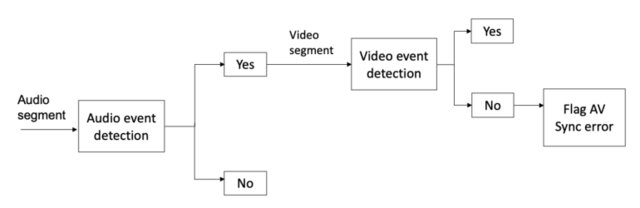
We present a new method and a large-scale database to detect audio-video synchronization(A/V sync) errors in tennis videos. A deep network is trained to detect the visual signature of the tennis ball being hit by the racquet in the video stream. Another deep network is trained to detect the auditory signature of the same event in the audio stream. During evaluation, the audio stream is searched by the audio network for the audio event of the ball being hit. If the event is found in audio, the neighboring interval in video is searched for the corresponding visual signature. If the event is not found in the video stream but is found in the audio stream, A/V sync error is flagged. We developed a large-scaled database of 504,300 frames from 6 hours of videos of tennis events, simulated A/V sync errors, and found our method achieves high accuracy on the task.

Joshua P Ebenezer*, Zaixi Shang*, Yongjun Wu, Hai Wei, Alan C Bovik
* Equal contribution
IEEE International Workshop on Multimedia Signal Processing (MMSP), 2020

We propose a new prototype model for no-reference video quality assessment (VQA) based on the natural statistics of space-time chips of videos. Space-time chips (ST-chips) are a new, quality-aware feature space which we define as space-time localized cuts of video data in directions that are determined by the local motion flow. We use parametrized distribution fits to the bandpass histograms of space-time chips to characterize quality, and show that the parameters from these models are affected by distortion and can hence be used to objectively predict the quality of videos. Our prototype method, which we call ChipQA-0, is agnostic to the types of distortion affecting the video, and is based on identifying and quantifying deviations from the expected statistics of natural, undistorted ST-chips in order to predict video quality. We train and test our resulting model on several large VQA databases and show that our model achieves high correlation against human judgments of video quality and is competitive with state-of-the-art models.

Joshua Peter Ebenezer, P Murali Krishna
IEEE Region 10 Conference (TENCON), 2019

This paper introduces a class of carrier recovery scheme based on simple trigonometric identities. We revisit carrier recovery schemes that have been in use for many years, and compare their relative performances using quantitative metrics. We show that trigonometric identities can be used to recover carriers faster and better than conventional control loop based schemes in special cases where there is a unique frequency locked relationship between the carriers and the pilot of the scheme. PLL and Costas loop based schemes have been carried over from analog systems and are now implemented on digital hardware without fully exploiting the advantages of digital systems, but we propose a simple scheme that can outperform these legacy methods in specific protocols, and be incorporated into modern receivers of any protocol having frequency-locked carriers of a pilot. We present results for the specific case of the FM-RDS protocol as an example.
Vikrant A Karale, Joshua P Ebenezer, Jayasree Chakraborty, Tulika Singh, Anup Sadhu, Niranjan Khandelwal, Sudipta Mukhopadhyay
Journal of Digital Imaging, 2019

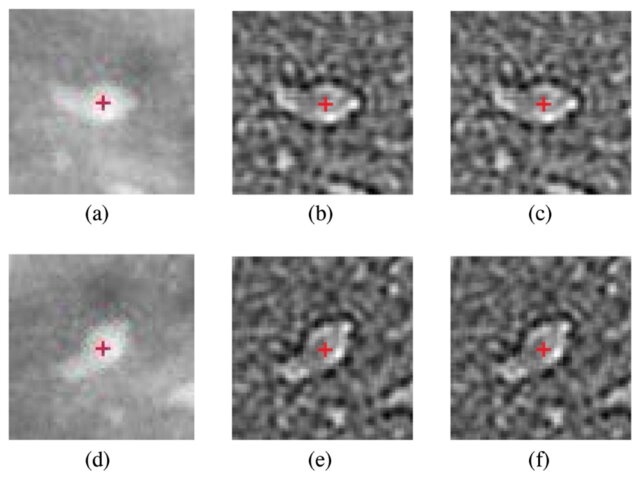
Breast cancer is the most common cancer diagnosed in women worldwide. Up to 50% of non-palpable breast cancers are detected solely through microcalcification clusters in mammograms. This article presents a novel and completely automated algorithm for the detection of microcalcification clusters in a mammogram. A multiscale 2D non-linear energy operator is proposed for enhancing the contrast between the microcalcifications and the background. Several texture, shape, intensity, and histogram of oriented gradients (HOG)–based features are used to distinguish microcalcifications from other brighter mammogram regions. A new majority class data reduction technique based on data distribution is proposed to counter data imbalance problem. The algorithm is able to achieve 100% sensitivity with 2.59, 1.78, and 0.68 average false positives per image on Digital Database for Screening Mammography (scanned film), INbreast (direct radiography) database, and PGIMER-IITKGP mammogram (direct radiography) database, respectively. Thus, it might be used as a second reader as well as a screening tool to reduce the burden on radiologists.

Joshua Peter Ebenezer, Bijaylaxmi Das, Sudipta Mukhopadhyay
European Signal Processing Conference (EUSIPCO), 2019

We present a method to restore a clear image from a haze-affected image using a Wasserstein generative adversarial network. As the problem is ill-conditioned, previous methods have required a prior on natural images or multiple images of the same scene. We train a generative adversarial network to learn the probability distribution of clear images conditioned on the haze-affected images using the Wasserstein loss function, using a gradient penalty to enforce the Lipschitz constraint. The method is data-adaptive, end-to-end, and requires no further processing or tuning of parameters. We also incorporate the use of a texture-based loss metric and the L1 loss to improve results, and show that our results are better than the current state-of-the-art.

Figure from Fog Removal from Videos
Fog Removal from Videos
Joshua Peter Ebenezer
Undergraduate Thesis, Indian Institute of Technology Kharagpur, 2019
Joshua Peter Ebenezer, Jagath C Rajapakse
arXiv preprint, 2018

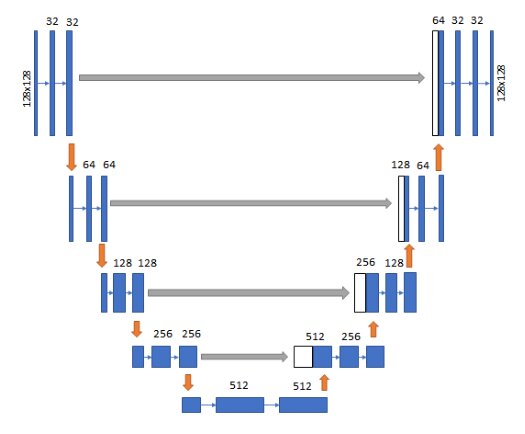
This paper summarizes the method used in our submission to Task 1 of the International Skin Imaging Collaboration's (ISIC) Skin Lesion Analysis Towards Melanoma Detection challenge held in 2018. We used a fully automated method to accurately segment lesion boundaries from dermoscopic images. A U-net deep learning network is trained on publicly available data from ISIC. We introduce the use of intensity, color, and texture enhancement operations as pre-processing steps and morphological operations and contour identification as post-processing steps.

Patents

2 public, 7 pending.

Figure from Image Alignment for Multi-Frame Fusion of Tetra or Other Image Data
Image Alignment for Multi-Frame Fusion of Tetra or Other Image Data
Joshua P Ebenezer, Haegeun Lee, Hamid Rahim Sheikh
US Patent Application 2025/0225667 A1, 2025

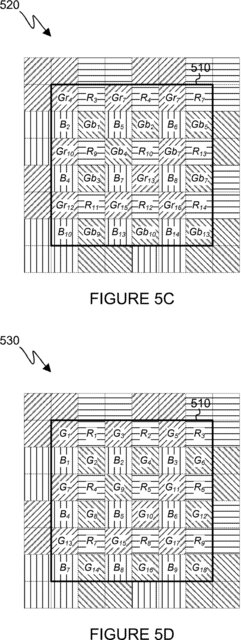
Non-Bayer color filter array (CFA) input images including reference and non-reference images each having a non-Bayer CFA pattern are obtained. Reference and non-reference luma images respectively corresponding to a reference Bayer-like pattern based on the reference image and a non-reference Bayer-like pattern based on the non-reference image are generated. A resolution of each luma image is approximately half a resolution of each input image. A smoothing operation is performed on the luma images to remove artifacts and generate filtered reference and non-reference luma images. Motion vectors based on the filtered luma images are identified, and the motion vectors and filtered luma images are upscaled to generate upscaled motion vectors and upscaled luma images. High-resolution refinement of the upscaled motion vectors is performed based on the upscaled luma images to generate a finalized motion vector, and the input images are aligned with one another based on the finalized motion vector.

Yongjun Wu, Joshua Peter Ebenezer, Sriram Sethuraman, Hai Wei, Zongyi Liu
US Patent 11,336,935 B1, 2022

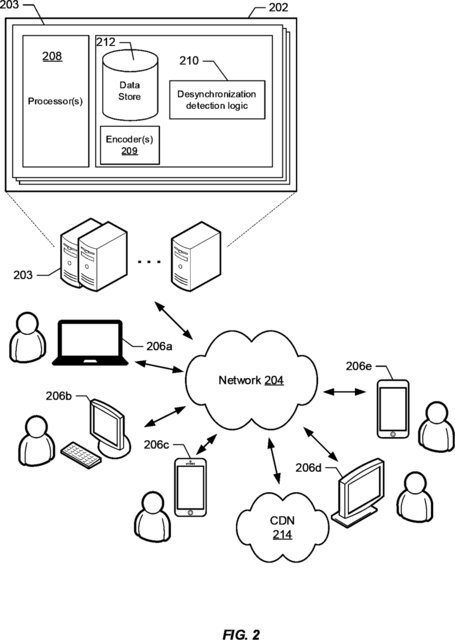
Techniques are described for detecting desynchronization between an audio stream and a video stream.

Other Projects

Course projects and reports.

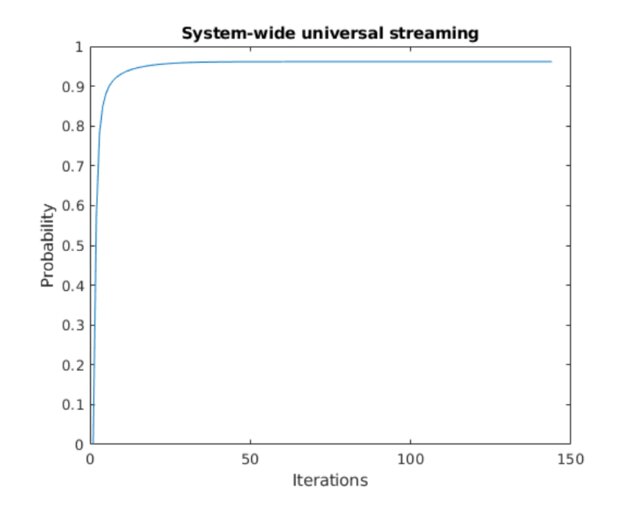
Abhinau K Venkataramanan, Joshua Ebenezer, Aniruddh Venkatakrishnan
Course project report, UT Austin, 2021

This system involves people/devices live streaming various channel data (J) from different servers. The server bandwidth, in itself, is insufficient to satisfy the streaming-rate for all the users viewing the channel. To overcome this issue, each user also redistributes the data it receives into the system thereby increasing the effective bandwidth of each channel. Viewing and uploading are strictly decoupled in this model, which was introduced in [1]. All allocations are implemented with the aim of maximizing Probability of Universal Streaming (PUS) which gives the probability that all users of a channel get sufficient bandwidth for uninterrupted viewing.

Joshua Peter Ebenezer
Final project report, Combinatorial Optimization, UT Austin, 2020

A combinatorial auction is a type of auction in which bidders can assign values to combinations of items, instead of only assigning values to individual items. These are useful in situations where bidders place more or less value to a combination of items than to the sum of the individual values of those items. In this project report, some of the main results in combinatorial auctions are studied in an expository fashion, with particular attention given to a subclass of combinatorial auctions called the submodular welfare problem.